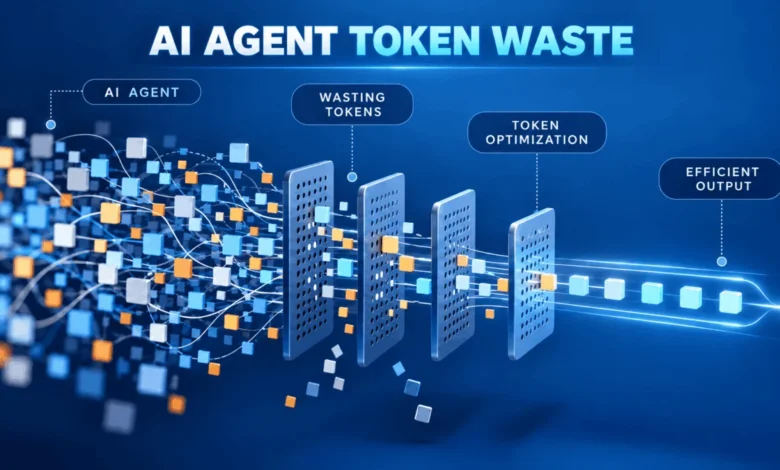
In the rapidly evolving landscape of generative artificial intelligence, the transition from a weekend prototype to a sustainable production system is frequently defined by a single, critical metric: the cost of inference. As organizations integrate autonomous AI agents into their core operational workflows, many engineers are discovering that token consumption does not scale linearly with task complexity; instead, inefficient architectural choices often lead to exponential increases in operational expenditure. When an agent treats its context window as an infinite ledger, the resulting "token bloat" degrades performance, inflates latency, and threatens the economic viability of AI deployments. This report outlines seven primary patterns of token wastage observed in enterprise AI systems and provides the necessary architectural frameworks to mitigate them.
The Problem of Contextual Bloat
The fundamental error in many current agent architectures is the conflation of "context" with "state." Context is the ephemeral, high-cost data packet transmitted to the Large Language Model (LLM) per inference call. State is the durable, serialized record of an agent’s progression, typically stored in a database. When engineers bypass persistent storage and attempt to keep the agent’s entire history within the active context window, they essentially force the model to re-process stale information during every single iteration. Data indicates that for agents running iterative reasoning loops, this "append-only" approach can lead to a 400% increase in token consumption within the first ten turns of a conversation.
1. The Append-Only Trap: Context Window Accumulation
The most prevalent architectural failure is the tendency to append every user message, tool observation, and intermediate reasoning step to a single array. As the array grows, the agent incurs a "quadratic tax," where the cost of processing the entire historical sequence is paid repeatedly.
The industry-standard solution is the implementation of a sliding context window paired with semantic rolling summarization. By maintaining a buffer of the last N turns and condensing older interactions into a compressed narrative summary, engineers can maintain continuity without the overhead of redundant data. However, this introduces a risk of "lossy" communication. To counter this, developers are increasingly deploying key-value lookup tools that allow the agent to fetch specific, high-fidelity data points—such as UUIDs or specific timestamps—directly from a database, bypassing the need to store them in the context window.
2. Inefficient Tool Result Ingestion
Autonomous agents frequently interact with third-party APIs that return verbose, machine-optimized JSON payloads. Integrating these raw outputs into an agent’s reasoning context is a major driver of waste. A single standard API response can contain thousands of tokens of metadata, most of which are irrelevant to the agent’s decision-making process.
Architectural remediation involves the insertion of a middleware transformation layer. This layer serves as a filter that strips null values, removes unnecessary keys, and reformats the remaining essential data into dense, human-readable YAML or Markdown. While this effectively reduces token count, developers must exercise caution; aggressive filtering can inadvertently remove critical pagination cursors or authorization headers, which are necessary for the agent to complete complex multi-step tasks.
3. Retrieval Thrash and the "Grep-and-Dump" Fallacy
In Retrieval-Augmented Generation (RAG) systems, a common, inefficient practice is "Grep-and-Dump" retrieval. This occurs when an orchestrator identifies a potential match for a query and proceeds to inject the entire document or file into the context window. This method is highly inefficient, often requiring the model to parse thousands of lines of irrelevant text to extract a single function or data point.
The modern shift is toward AST-aware (Abstract Syntax Tree) retrieval. By parsing code into a live call graph during the indexing phase, systems can provide the agent with only the relevant structural units—such as function signatures and immediate dependencies—rather than entire files. This reduction can bring token requirements down from thousands to a few hundred per retrieval, significantly improving both latency and accuracy.
4. Static Tool Schema Bloat
Many agent frameworks default to injecting the entire tool registry into the prompt for every turn. While manageable for systems with three or four tools, this becomes a critical failure point for agents with 50 or more functions. The model is forced to interpret massive schema definitions regardless of the task at hand.
The solution is the adoption of a finite state machine (FSM) to govern dynamic tool injection. By restricting the available toolset to those relevant to the agent’s current operational phase—such as discovery, execution, or verification—developers can minimize the prompt’s footprint. The primary trade-off here is the impact on KV caching. Because the tool subset changes, the LLM provider cannot maintain a consistent cache prefix, potentially increasing latency in exchange for lower token usage.
5. Unbounded Chain-of-Thought Loops
Autonomous agents, when left without hard guardrails, are prone to "reasoning loops" where they repeatedly attempt failed actions. In a production environment, this can lead to massive output token consumption, as the agent documents its own failures and retries.
Engineers are now implementing "orchestrator-level circuit breakers." These mechanisms enforce strict retry limits and cap the total output token budget per action. If an agent hits a threshold, the orchestrator triggers an intervention—either by pivoting to a deterministic fallback or escalating the issue to a human supervisor. This is widely considered a mandatory guardrail for any agent performing high-stakes tasks in a production environment.
6. The Necessity of KV Cache Optimization
LLM providers now offer prompt caching, which allows for the storage of the key-value representations of common prefixes. However, this feature is often rendered useless by poor prompt structuring. If an engineer places dynamic variables—such as current timestamps or user-specific identifiers—at the beginning of a prompt, they break the cache boundary.
The industry-recommended architecture requires a "static-to-dynamic gradient." Organizations must place static content, such as system prompts and organizational style guides, at the top of the request. By ensuring that the static prefix remains identical across all calls, developers can maximize cache hits and realize significant reductions in both inference costs and latency.
7. Monolithic Routing and the Frontier Model Premium
A final, critical error is the "monolithic routing" of all tasks through a single, high-cost frontier model. Using an advanced model to perform simple tasks like log summarization or intent classification is economically unsustainable at scale.
The solution is the implementation of a cascaded LLM router. Under this model, a lightweight, high-speed model handles basic structural tasks and classification. If the initial model determines that the task requires advanced reasoning, it routes the request to a frontier model. While this introduces a risk of misrouting, the cost savings for high-volume applications often justify the complexity of the routing logic.
Implications for Long-Term System Stability
The implications of these optimizations extend far beyond monthly billing. As AI systems mature, token management becomes a proxy for data hygiene. Accumulating redundant context and outdated API documentation within an agent’s memory leads to "memory rot," where the agent struggles to reconcile its internal state with reality.
By day 100 of a production deployment, the architectural choices made in the initial phase often dictate the system’s resilience. Rigid, optimized, and deterministic systems are significantly less prone to the "drift" that plagues poorly architected agents. The focus of the engineering community is shifting toward ensuring that every token sent is a token that contributes directly to the agent’s goal, transforming token efficiency from a cost-cutting measure into a cornerstone of robust AI infrastructure.
Related posts: