The Illusory Edge: How Artificial Intelligence is Flooding Retail Quantitative Trading with False Discoveries

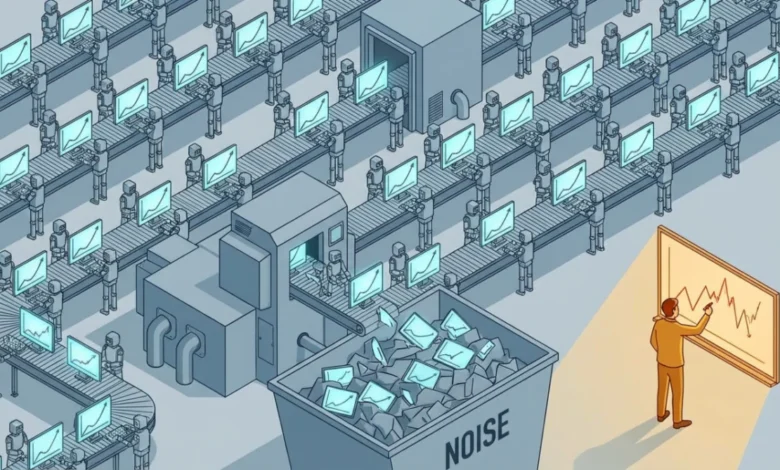
The democratization of financial technology has historically been heralded as a triumph for retail investors, lowering barriers that once kept complex trading strategies restricted to institutional desks and hedge funds. However, the rapid integration of artificial intelligence and large language models (LLMs) into retail quantitative trading has introduced an unprecedented systemic risk: the mass production of statistically hollow, overfitted trading models. While generative AI enables users to conceptualize, code, and backtest a sophisticated trading strategy within minutes, industry analysts and veteran quantitative researchers warn that the vast majority of these AI-generated strategies are destined to lose money in live markets.
This modern phenomenon represents a significant escalation of a well-documented statistical trap. For decades, systematic traders have fallen victim to the "Backtest Cycle of Doom," a repetitive loop of tweaking parameters, running backtests, and optimizing models against historical data until a seemingly profitable equity curve emerges. What was once a tedious, manual process requiring weeks of programming and data acquisition can now be executed thousands of times per hour via automated prompt engineering. Consequently, the financial landscape is witnessing an unprecedented influx of false discoveries—strategies that appear infallible on paper but possess no structural validity in reality.
The Mechanics of the False Discovery Epidemic
To understand the scale of the current vulnerability, one must examine the fundamental mechanics of statistical testing and data mining. In classical statistics, the multiple testing problem dictates that as the number of hypotheses tested increases, the probability of encountering a false positive approaches certainty. If a researcher tests one thousand independent parameter combinations at a five percent significance level, approximately fifty false positives will naturally appear purely by chance.
Before the widespread availability of generative AI, computational friction acted as a natural safeguard against excessive data mining. Building, debugging, and testing models required specialized knowledge of languages like Python or C++, database management, and infrastructure maintenance. These technical prerequisites forced traders to deliberate carefully over every hypothesis.
Generative AI has systematically dismantled that friction. Today, an individual with a basic subscription to an LLM can generate 20,000 parameter variations in a single afternoon without writing a single line of code. The AI readily complies, outputting pristine scripts and glowing equity curves that simulate astronomical returns. However, the model lacks the capacity to distinguish between genuine economic phenomena and statistical noise. Because LLMs are trained on vast corpuses of internet data—which includes a high volume of unverified trading forums, pseudoscientific technical analysis blogs, and flawed academic papers—they frequently synthesize and validate the average of the internet’s worst financial ideas.
Historical Context and Parallel Industries
The flood of false discoveries driven by computational efficiency is not entirely unprecedented. Similar technological shocks have reverberated through other knowledge-based sectors over the past two decades. In academic research, the advent of cheap, high-performance computing and automated statistical software packages led to a replication crisis across psychology, medicine, and economics. Researchers found it trivially easy to "p-hack"—manipulating data or continuously running tests until reaching a statistically significant result.
Similarly, during the early 2010s democratization of factor investing, quantitative finance experienced a proliferation of newly discovered market anomalies. Academic literature was flooded with hundreds of novel equity factors designed to beat the market. Yet, as institutional allocators and subsequent academic studies demonstrated, the vast majority of these factors decayed rapidly upon live implementation because they were merely the product of extensive data dredging rather than genuine structural market inefficiencies.
The current retail AI boom represents the third and most pervasive wave of this phenomenon. By lowering the technical barrier to entry to virtually zero, platforms powered by generative AI have decentralized data mining, allowing millions of retail participants to engage in large-scale backtest overfitting from standard consumer laptops.
The Missing Foundation: The Theory of Edge
Veteran quantitative researchers argue that the root cause of failure among AI-assisted retail traders lies in a fundamental misunderstanding of what constitutes a trading edge. In professional quantitative shops, the development process almost never begins with data or code. Instead, it begins with an economic question: Why would the market pay me to do this trade?
Answering this question requires formulating a rigorous "theory of edge"—an understanding of the structural, behavioral, or institutional reasons why a persistent inefficiency exists. Genuine edges are typically born from well-documented market mechanics, such as:
- Institutional constraints (e.g., regulatory mandates restricting certain asset classes)
- Behavioral biases (e.g., loss aversion, disposition effect, or overreaction to news)
- Structural liquidity imbalances (e.g., mandatory rebalancing periods for index funds)
For example, momentum trading is a universally recognized phenomenon across multiple asset classes. However, automated systems that discover momentum purely through data mining—without understanding the underlying human and institutional behaviors that drive it, such as career risk among fund managers or slow capital reallocation—invariably fall into the trap of over-optimizing parameters to past price action. When the underlying market regime shifts, these overfitted models experience catastrophic drawdowns.
Artificial intelligence tools inherently lack a theory of edge. While they excel at syntax, code generation, and pattern matching, they cannot independently evaluate whether a market inefficiency is structural or transient. Consequently, they serve to accelerate the creation of what quantitative researchers describe as "more of the disease, faster"—amplifying the procedural mistakes of novice traders under the guise of technological advancement.
Industry Implications and the Rise of Cognitive Scarcity
As the market adjusts to the proliferation of AI-generated trading strategies, the traditional definitions of scarcity within the financial industry are undergoing a structural inversion. For decades, the primary competitive moats in quantitative finance were computational power, access to clean historical data, and advanced programming capabilities.
Today, those resources have largely been commoditized. Computing power is accessible via cloud infrastructure, alternative data sets are widely available, and generative AI can write production-ready code on demand. Consequently, the true scarce commodities in modern trading are human judgment, skepticism, research discipline, and a rigorous understanding of statistical uncertainty.
Market analysts and institutional risk managers suggest that the long-term impact of AI on retail trading will not be a massive democratization of wealth creation, but rather a widening performance gap. While millions of retail participants will continue to produce visually impressive backtests that ultimately fail in live production, the successful systematic traders will be those who use AI strictly as a technical assistant while retaining sole responsibility for the conceptual validity of their strategies.
Ultimately, the fundamental rule of financial markets remains unaltered by technological progress: if a trading strategy is easy to discover, computationally optimized to the past, and devoid of a sound economic rationale, it is almost certainly a mirage. In the age of artificial intelligence, the most valuable tool a trader can possess is not a better prompt, but the discipline to ask the difficult questions before writing a single line of code.