Benchmarking Scikit-Ollama vs. Groq-Backed Scikit-LLM: Speed, Cost, and Accuracy

The rapid proliferation of Large Language Models (LLMs) has forced developers to confront a critical architectural decision: whether to deploy inference locally or rely on managed cloud-based APIs. As organizations strive to integrate generative AI into production workflows, the criteria for selecting an infrastructure provider have narrowed down to three primary pillars: latency, cost efficiency, and task accuracy. A practical benchmarking framework, utilizing the Scikit-Learn ecosystem, now offers a standardized method to quantify these trade-offs, pitting local open-source models against high-performance cloud-based inference engines.
The Architectural Divide: Local vs. Cloud Inference
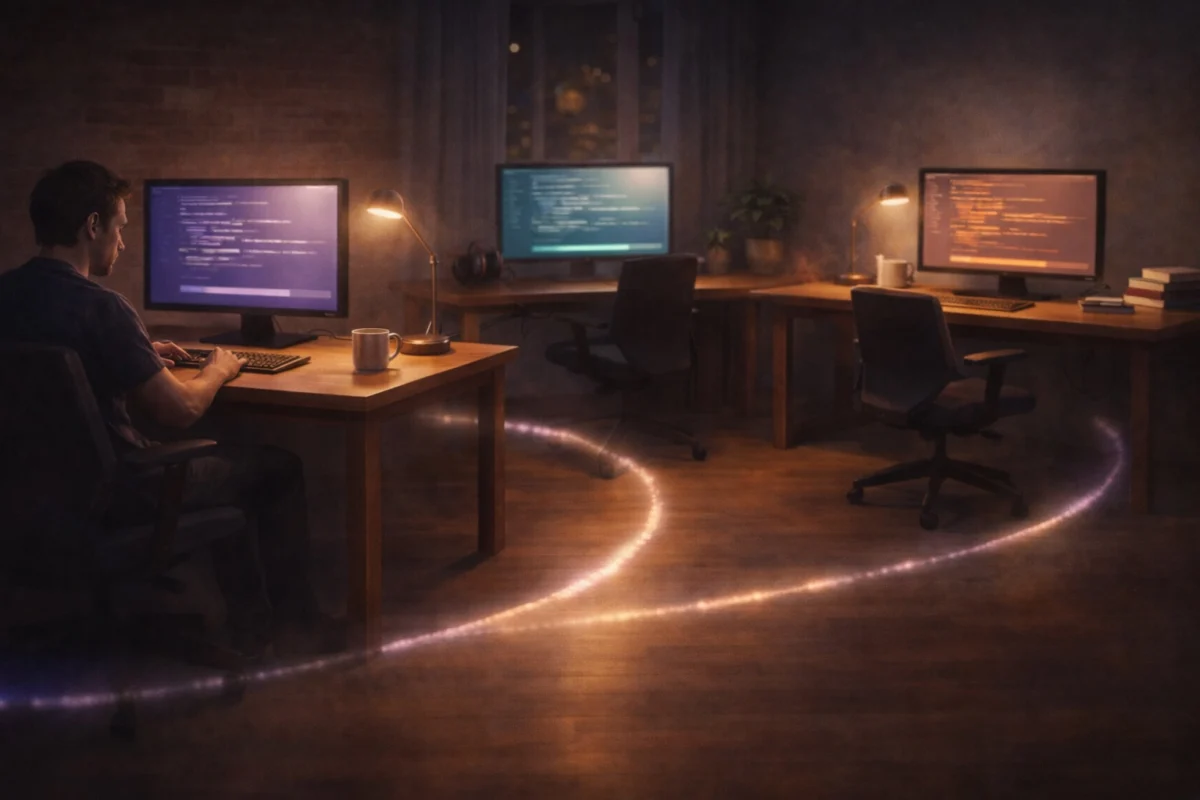
The debate between local and cloud-based LLM deployment is not merely a technical preference but a strategic business decision. Local inference, typically facilitated by tools like Ollama, keeps data within the perimeter of a private network. This approach is favored in sectors with stringent data privacy requirements, such as finance, healthcare, and legal services. However, it imposes significant demands on local hardware, specifically regarding VRAM (Video RAM) and GPU compute capabilities.
Conversely, cloud-based inference—often accessed through providers like Groq—leverages specialized hardware (such as LPU or Tensor Processing Units) to deliver near-instantaneous responses. While this minimizes the local hardware footprint, it introduces dependencies on network stability and raises concerns regarding data sovereignty. By using standardized wrappers like Scikit-Ollama and Scikit-LLM, developers can now run identical classification tasks on both architectures, creating a controlled environment for empirical comparison.
Setting the Stage: The Benchmarking Framework
To ensure a fair evaluation, the benchmark requires a unified pipeline that adheres to the Scikit-Learn API—the industry standard for machine learning workflows. The methodology involves a "Zero-Shot" classification task, where an LLM is asked to categorize text without having been explicitly trained on the specific dataset.
The process begins by configuring the local environment. Using Ollama, a user can pull an open-source model such as Llama 3. This model resides entirely on the host machine, eliminating per-token costs. The second leg of the benchmark involves configuring Scikit-LLM to route requests to the Groq cloud infrastructure. By modifying the base URL of the API requests, developers can swap the provider from OpenAI to Groq, effectively utilizing Groq’s high-throughput hardware while maintaining the same Pythonic interface.
Chronology of the Setup Process
- Library Initialization: The process initiates with the installation of
scikit-llmandscikit-ollama. These wrappers act as an abstraction layer, allowing the developer to treat an LLM as a Scikit-Learn estimator. - Ollama Server Deployment: For local benchmarks, the Ollama server is initialized in the background. This involves a cold-start period where the model weights are loaded into memory.
- Data Preparation: A standardized set of text samples is created, accompanied by ground-truth labels. This ensures that both the local model and the cloud model are evaluated on identical inputs.
- Execution and Timing: A helper function,
benchmark_estimator, is employed to wrap the.fit()and.predict()methods. This function utilizes high-precision system timers to record the exact latency of the classification process.
Comparative Performance Analysis
Empirical results from these benchmarks reveal stark differences in performance metrics. In initial tests, local deployment of Llama 3 shows latency figures in the range of 80 seconds for a small batch of inputs, largely due to the overhead of local GPU processing and memory management. In contrast, the Groq-backed cloud pipeline can process the same workload in approximately 2 seconds.
The accuracy of these models remains competitive, with both architectures consistently delivering high performance on sentiment analysis tasks. However, the "real-world" implication is that local models require constant hardware maintenance and scaling, whereas cloud models scale elastically based on demand.
Economic and Operational Implications
The cost dimension of this comparison is evolving. While local hardware is often perceived as "free," the total cost of ownership (TCO) includes electricity, hardware depreciation, and engineering time spent on infrastructure management. Cloud providers, meanwhile, are increasingly adopting "free-tier" models or competitive pay-per-token pricing that can be more economical than maintaining a dedicated local GPU cluster for intermittent workloads.
From an operational standpoint, the ability to switch between these backends using only a few lines of code—thanks to the modular nature of Scikit-LLM—provides businesses with "model agility." If a cloud provider suffers an outage, the application can theoretically failover to a local instance, provided the local hardware is appropriately provisioned.
Security and Data Privacy Considerations
A primary driver for the adoption of local LLM pipelines is data privacy. In a regulated environment, transmitting sensitive customer data to a third-party API is often prohibited by internal compliance policies. The benchmark results suggest that while local inference is slower, it provides a "zero-trust" environment where data never leaves the premises.
Conversely, the speed of cloud-based inference is a game-changer for latency-sensitive applications, such as real-time customer support chatbots or automated financial trading sentiment analysis. The industry trend suggests a hybrid future: utilizing cloud inference for non-sensitive, high-speed tasks and reserving local, private infrastructure for high-stakes, sensitive data processing.
Broader Industry Impact
The benchmarking of LLMs through traditional machine learning frameworks marks a significant maturity point in the AI development lifecycle. It signals that LLMs are no longer experimental research tools but standard components of a production software stack. By moving away from proprietary, monolithic APIs toward interoperable, modular pipelines, developers gain the flexibility to optimize their infrastructure based on shifting project requirements.
Furthermore, as the gap between open-source model capabilities and closed-source proprietary models narrows, the advantage of using local inference grows. Companies that invest in the infrastructure to support local LLM benchmarking today are better positioned to pivot as the landscape of open-weights models improves in both efficiency and performance.
Concluding Insights
The integration of scikit-ollama and scikit-llm into the development toolkit demonstrates that rigorous scientific evaluation is possible even within the complex world of generative AI. By systematically comparing local and cloud architectures, engineers can bypass marketing claims and focus on the data.
As we look toward the future, the ability to perform these benchmarks will likely become a core competency for AI engineers. The trade-off between the immediate, low-latency performance of cloud providers like Groq and the data-sovereign, predictable nature of local hardware will continue to define the architecture of the next generation of AI-native applications. Developers are encouraged to maintain a "provider-agnostic" approach, ensuring that their code remains portable and their infrastructure choices remain informed by empirical evidence rather than speculative performance.
In summary, the choice between local and cloud is not a binary one but a spectrum. Through standardized benchmarking, organizations can find their optimal position on that spectrum, ensuring that their AI deployments are not only accurate but also cost-effective and operationally resilient. The path forward involves continuous testing, modular design, and a clear understanding of the specific constraints of the target application, whether it resides on a local workstation or in a distributed cloud environment.