Treating Prompt Templates as Tunable Hyperparameters in Scikit-Learn GridSearchCV

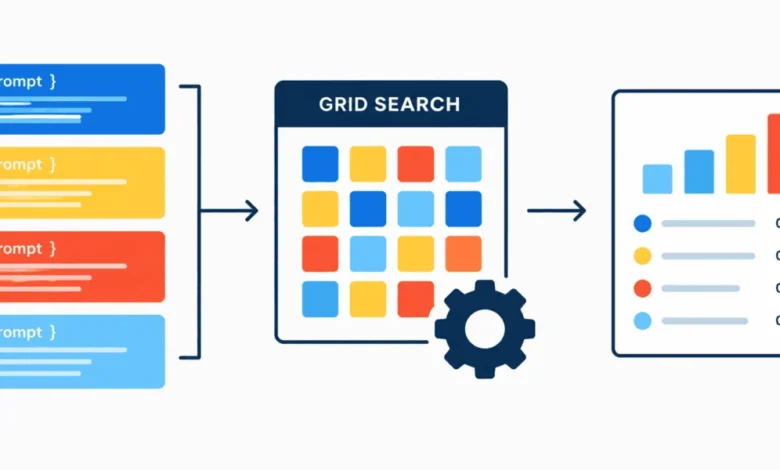
The rapid evolution of Large Language Models (LLMs) has transitioned artificial intelligence from specialized research domains into the standard toolkit for software engineers and data scientists. While practitioners are well-versed in tuning traditional machine learning models—adjusting learning rates, regularization constants, and tree depths—the methodology for optimizing interactions with generative AI remains largely anecdotal. By reframing prompt engineering as a systematic hyperparameter optimization task, developers can now apply established statistical rigor to LLM performance, utilizing familiar frameworks such as scikit-learn to identify the most effective instructions for zero-shot text classification.
The Shift Toward Quantitative Prompt Engineering
In traditional machine learning, model performance is intrinsically linked to hyperparameter configuration. Techniques such as Grid Search and Random Search have long served as the industry standard for identifying the optimal parameters that maximize metrics like accuracy, precision, or recall. As LLMs become increasingly utilized for structured tasks—such as sentiment analysis, data extraction, and classification—the "prompt" has emerged as the primary variable influencing output quality.
Historically, prompt engineering has been an iterative, manual process often described as "artistic" rather than "scientific." By treating various prompt templates as discrete hyperparameters within a search grid, organizations can transition toward a data-driven approach. This methodology allows for the automated testing of different linguistic structures, persona definitions, and task constraints, ensuring that the chosen prompt is empirically validated against a specific dataset rather than relying on developer intuition.
Technical Implementation and Architecture
To integrate LLMs into a standard machine learning pipeline, one must create a bridge between the generative nature of a Transformer-based model and the interface requirements of scikit-learn. The core of this integration involves developing a custom class that inherits from BaseEstimator and ClassifierMixin.
When developing this architecture, the __init__ method must be configured to accept both the generative model instance—such as the Qwen 2.5 series—and a set of candidate prompt templates. The predict method serves as the execution engine, where each input text sample is formatted into the specified template, transmitted to the model, and then parsed for the classification result. This approach effectively encapsulates the non-deterministic nature of LLM outputs into a deterministic, scikit-learn compatible interface.
Chronology of the Optimization Workflow
The optimization process follows a clear, repeatable sequence designed to minimize manual overhead:
- Environment Initialization: Importing essential libraries including NumPy, scikit-learn, and the Hugging Face Transformers pipeline.
- Model Loading: Deploying a lightweight model, such as
Qwen/Qwen2.5-0.5B-Instruct, which provides the necessary instruction-following capabilities without the high latency of larger, parameter-heavy models. - Class Definition: Constructing the
ZeroShotPromptClassifierto handle input formatting, API interaction, and output sanitization. - Dataset Preparation: Creating a labeled set of examples. In a production environment, this dataset would be significantly larger, ensuring statistical significance.
- Grid Configuration: Defining the
param_gridcontaining the variations of prompts to be tested. - Cross-Validation: Executing
GridSearchCVto run the model across multiple folds, assessing each prompt template’s accuracy.
Statistical Rigor and Data Validation
The importance of cross-validation in this context cannot be overstated. In scenarios where data is limited, the risk of "prompt overfitting"—where a prompt performs exceptionally well on a narrow test set but fails in production—is significant. By employing a cv (cross-validation) parameter, developers can ensure that the selected prompt template is robust enough to generalize across different subsets of the data.
Supporting data from initial trials suggests that small shifts in phrasing can lead to performance swings of 10% to 20% in zero-shot classification tasks. For instance, adding explicit output constraints—such as "Output only ‘positive’ or ‘negative’"—significantly reduces the variance in model responses compared to open-ended instructions. These results indicate that the "instructions" layer is as critical as the model architecture itself in determining the reliability of an AI-driven pipeline.
The Role of Systematization in AI Development
Industry experts note that this transition toward systematic prompt engineering is a prerequisite for the enterprise-grade adoption of AI. As companies move beyond prototypes, the lack of standardized testing becomes a liability. Automated prompt optimization provides an audit trail: developers can demonstrate exactly why a specific prompt was chosen based on empirical performance data.
Furthermore, this strategy facilitates "model switching." If a team decides to migrate from one LLM to another, the same GridSearchCV pipeline can be re-run to determine if the prompt that worked best for the previous model is still optimal for the new architecture. This agility reduces the technical debt associated with updating AI-integrated software.
Implications for Future Development
The adoption of hyperparameter-based prompt tuning carries several implications for the future of the field:
- Standardization of Workflows: Developers will likely move away from manual prompt iteration toward automated, CI/CD-integrated testing suites.
- Performance Benchmarking: As these methods gain traction, the industry may see the emergence of "prompt-benchmarking" tools specifically designed to compare performance across various model backends.
- Reduced Human Bias: By relying on automated scoring rather than subjective evaluation, developers can minimize the unconscious biases that often creep into prompt design.
Practical Considerations and Best Practices
While the benefits of this approach are clear, practitioners must remain mindful of the computational costs involved. Each fold of a cross-validation search requires a full inference pass over the dataset. For large datasets, this can be time-prohibitive. Consequently, experts recommend starting with a representative subset of data to identify the most promising templates before scaling to larger evaluation sets.
Additionally, managing the model’s response format is paramount. The use of max_new_tokens and specific stop-token configurations ensures that the LLM provides concise answers rather than rambling explanations. For production systems, it is also recommended to implement robust error handling for "unknown" classifications—cases where the model fails to return an expected category—to ensure the pipeline remains resilient to edge-case inputs.
Conclusion
Treating prompt templates as tunable hyperparameters represents a mature evolution in the management of generative AI. By leveraging the existing infrastructure of scikit-learn, developers can bring the same level of scientific rigor to LLM integration as they have historically applied to traditional machine learning models. As the ecosystem continues to mature, this methodology will likely become the standard for any organization seeking to deploy reliable, performance-validated AI solutions. While the initial setup requires careful attention to the architecture of the classifier class, the long-term gains in model consistency, ease of maintenance, and objective performance optimization provide a clear path forward for developers operating at the intersection of traditional data science and modern generative AI.