A Gentle Introduction to Model Distillation and the Escalating Industry Conflict

In the rapidly evolving landscape of artificial intelligence, the most sophisticated models—such as OpenAI’s GPT-4, Anthropic’s Claude 3.5, and Google’s Gemini—represent the pinnacle of computational achievement. These models, often characterized by hundreds of billions of parameters, require immense data centers and massive energy expenditure to function. This creates a fundamental paradox: the most capable AI tools are often the least portable, making them impossible to deploy on edge devices like smartphones or in environments with limited latency and compute budgets. To bridge this gap, the AI industry has turned to model distillation, a process that has evolved from a niche optimization technique into a primary, and increasingly contentious, battleground for intellectual property and competitive advantage.
The Mechanism of Knowledge Transfer
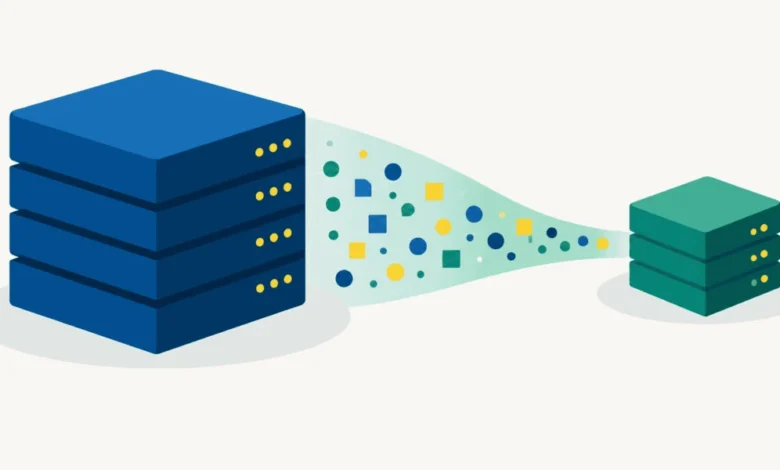
At its core, model distillation is the art of training a smaller, more efficient "student" model to mimic the performance of a larger, "teacher" model. The traditional methodology, formalized by Geoffrey Hinton and his colleagues in 2015, moved beyond simple binary classification. In standard training, a model is fed "hard labels"—for instance, identifying an image as either a "dog" or a "cat." However, this binary approach discards the subtle, relational nuance that a massive model captures during its training phase.
When a teacher model evaluates an image, it produces a probability distribution—identifying that an image is 85% likely to be a dog, 13% a cat, and 2% a wolf. This distribution contains what researchers call "dark knowledge": the hidden relationships between concepts that are invisible to raw, binary data. By forcing a student model to learn from these soft probability distributions, rather than just the final answer, developers can transfer the teacher’s generalization capabilities into a much smaller footprint. To facilitate this, engineers employ "temperature scaling," a mathematical trick that flattens the probability distribution, making the subtle relationships between classes more prominent and easier for the student to absorb.
Evolution for Large Language Models
While classical distillation was effective for fixed-output classification, the rise of Large Language Models (LLMs) necessitated a shift in strategy. LLMs operate on a sequential, token-by-token basis across massive vocabularies, rendering traditional logit-based distillation difficult to apply in black-box environments. Consequently, the industry has gravitated toward three primary methodologies:
- Synthetic Data Distillation: This has emerged as the industry standard. A powerful teacher model generates high-quality, synthetic datasets—such as chains of thought, code snippets, or structured reasoning—which are then used to train a smaller model. This method requires only API access, making it highly scalable and independent of the teacher’s internal architecture.
- Feature Distillation: This approach involves the student model mimicking the internal activation patterns of the teacher’s intermediate layers. While highly effective, it requires "white-box" access to the teacher model’s weights, limiting its use to internal organizational workflows.
- Logit-Based Distillation: A direct application of the classical framework at the token level, this method also requires deep internal access and is primarily utilized by organizations managing their own model families.
The Rise of Unauthorized Distillation
While distillation is a standard engineering practice—evidenced by Meta’s Llama 3.1, which is explicitly designed to serve as a teacher for smaller model variants—the practice has recently crossed into a contentious legal and ethical gray area. Throughout 2026, the industry saw a surge in allegations regarding "unauthorized distillation," where companies allegedly harvested the outputs of proprietary models to build competing products without the original developer’s consent.
Chronology of Escalation (2026):
- April 2026: During legal testimony, Elon Musk admitted under oath that xAI had utilized OpenAI’s models to assist in the training of Grok, characterizing the practice as standard industry behavior.
- Early 2026: OpenAI submitted a formal memo to the U.S. House Select Committee on China, alleging that the firm DeepSeek had employed obfuscated routing techniques to systematically harvest GPT-4’s capabilities.
- Mid-2026: Anthropic identified a sophisticated operation involving 24,000 fake accounts that generated over 16 million queries to Claude. The activity specifically targeted the model’s agentic reasoning and tool-use capabilities.
- June 2026: Anthropic publicly accused Alibaba’s Qwen lab of conducting a large-scale harvesting campaign, claiming 28.8 million exchanges were used to distill Claude’s knowledge into their own models. Alibaba denied these allegations.
- Ongoing: Google’s Threat Intelligence Group disclosed the disruption of multiple distillation attacks involving over 100,000 prompts, signaling that the threat is pervasive across the entire ecosystem.
Implications and Economic Impact
The core of the controversy lies in the disparity between development costs and replication costs. While DeepSeek reported that training its V3 model cost approximately $5.6 million, independent analysis by firms such as SemiAnalysis suggests the actual value of the research and infrastructure involved exceeds $1 billion. If unauthorized distillation allows a company to bypass the heavy R&D phase of training a frontier model, it effectively externalizes the cost of innovation onto the original developers.
Furthermore, the legal landscape remains remarkably underdeveloped. Because AI outputs generally do not qualify for copyright protection under current U.S. law, developers are left relying on Terms of Service (ToS) agreements. These agreements are difficult to enforce when the entities involved operate across international jurisdictions.
The Path Forward: Technical and Strategic Defenses
The industry is currently in an arms race between model owners and those seeking to distill them. Technical defenses, such as output watermarking, anomaly detection, and aggressive rate limiting, are being deployed with increasing frequency. However, these solutions are imperfect; watermarks can be stripped through fine-tuning, and restrictive rate limiting risks alienating legitimate enterprise customers.
The broader implication is that the tension between accessibility and security is reaching a breaking point. As models become more capable, their outputs become more "valuable" as training data. If developers cannot protect their intellectual property, they may be forced to move toward more closed, restricted, or tiered access models, potentially slowing the democratization of AI.
As of late 2026, no forensic audit has been independently verified, and no court has issued a definitive ruling on the legality of large-scale synthetic data harvesting. Until such legal precedents are established, model distillation will remain a double-edged sword: a vital tool for making powerful AI accessible to the masses and a major source of friction in the competitive, high-stakes race for global AI dominance. The structural problem—that a model’s best output is also its most vulnerable point—remains an unsolved riddle at the heart of modern machine learning.